

WeVisOne-VL-2B for LiteRT-LM
This repository is a conversion of tencent/WeVisOne-VL-2B to LiteRT-LM, made with litert-torch 0.10.0 for LiteRT-LM 0.18.1: on a Galaxy S26 GPU, WeVisOne-VL-2B_int8.litertlm answers a question about a 512 × 512 picture with its first token after 1.26 s and then writes 21.1 tokens per second (2026-10-31), and on the test questions that have a known answer it is right at least as often as the larger float16 file, WeVisOne-VL-2B_f16.litertlm.
tencent/WeVisOne-VL-2B is a vision-language model by WeChat Vision, Tencent, built on Qwen3-VL. It answers detection, referring, pointing, counting and OCR requests as structured text: boxes and points are the coordinate tokens <0> … <1000>, thousandths of the picture's width and height. Neither .litertlm file does segmentation or matting: those need the source model's 9.5M-parameter pixel decoder, which they do not contain.
| File | Bytes | sha256 | Weights |
|---|---|---|---|
WeVisOne-VL-2B_int8.litertlm |
2,913,946,112 | a6e5750f472b111ac116f27d9434c6b819a3d29309b76805135dee4496292fe8 |
int8 in the 28-layer decoder and the token embedder, float16 in the vision encoder and adapter |
WeVisOne-VL-2B_f16.litertlm |
4,899,179,008 | 97f29a6a1b672ad09afe33ee8c41589f62bac19a46092458bc4c96ef3f26adcb |
float16 in every graph |
Each file holds the vision encoder, the vision adapter, the token embedder and the 28-layer decoder, and the source repository's own tokenizer.json; the vision encoder and adapter are the same bytes in both. Each tells LiteRT-LM to run it as a single-picture vision-language model (its fast_vlm model type), with 2,048 tokens of context for the prompt and the answer. Neither declares an activation type, so on a GPU LiteRT-LM runs the decoder at its default float16 activations (and the vision encoder at its default float32).
Which file
- Galaxy S26 (GPU):
WeVisOne-VL-2B_int8.litertlm. In one session that alternated the two files, it took 1.26 s to the first token of a picture question and decoded 21.1 tokens per second, against 1.54 s and 12.9 tokens per second for the float16 file, and its process peaked at 2.70 GB of memory against 6.86–6.90 GB. - Pixel 8a (CPU):
WeVisOne-VL-2B_int8.litertlm. 13.58 s to the first token of a picture question, 8.0 tokens per second. The float16 file was not started on this 8 GB phone. On its GPU our test harness stopped the engine creation of the int8 build marked * when the phone's free memory fell below its limit; the int8 file was not started there (Limits: Memory). - Mac M4 Max (GPU):
WeVisOne-VL-2B_int8.litertlm. 0.29 s and 113.3 tokens per second, against 0.30 s and 81.4 tokens per second for the float16 file, at 3.85 GB of memory against 8.0 GB. On the Mac CPU the int8 build marked * took 4.64 s and decoded 26.8 tokens per second, against 4.85 s and 12.6 for the float16 file. WeVisOne-VL-2B_f16.litertlm: pick it on a Galaxy S26 GPU or a Mac when you want answers that stay closer to the original PyTorch model's (of the original's 44 points on 29 test questions it reproduces 35 on the Galaxy S26 GPU, the int8 file 28; see Correctness). It needs 6.9 GB on the Galaxy S26 GPU and runs at 12.9 tokens per second there; it was not started on the 8 GB Pixel 8a.
Use it
Download the file for your device (Which file, above). Before you send a picture, turn it upright from its EXIF orientation and stretch it to 512 × 512 with Pillow's BICUBIC filter, without padding or cropping, so that the coordinates map back onto the upright picture by its width and height. Neither Pillow's Image.open nor LiteRT-LM applies the EXIF orientation by itself. Every result on this card was measured on pictures resized that way and sent as PNG files (none of the test pictures is stored rotated; the upright step was checked on a copy tagged as rotated). Do the resize yourself: LiteRT-LM 0.18.1 stretches a picture of another size to 512 × 512 with its own filter (stb's Catmull-Rom), and an int8 build of this model that also declares float32 GPU activations, given the original pictures to resize that way, gave the identical answer text as with Pillow's pictures to only 9 of 29 questions on the Mac GPU and to 1 of 29 on the Mac CPU. Neither published file was run that way. Other resizing (Android's bitmap scaling, for example) and JPEG-compressed 512 × 512 pictures were not tested.
pip install "litert-lm==0.18.1" pillow
python3 -c "from PIL import Image, ImageOps; ImageOps.exif_transpose(Image.open('photo.jpg')).convert('RGB').resize((512, 512), Image.BICUBIC).save('photo_512.png')"
litert-lm run WeVisOne-VL-2B_int8.litertlm --backend gpu --vision-backend gpu --attachment photo_512.png --prompt "Locate all the instances that match the following description: truck. crane."
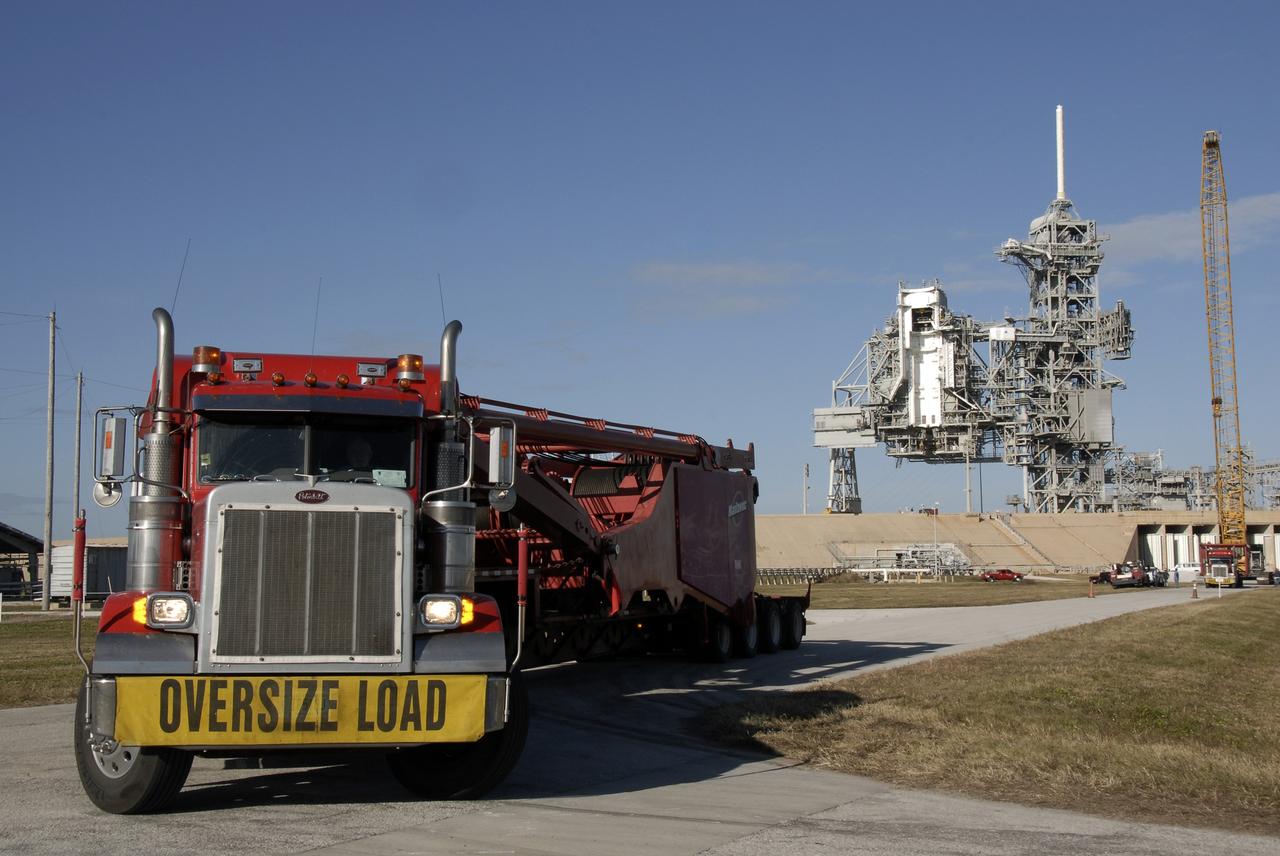
On a Mac M4 Max, with NASA's photo KSC-08pd3809 as photo.jpg, this prints <ref>truck</ref><box><60><359><608><951></box>, <ref>crane</ref><box><939><152><1000><683></box>: the truck spans 6.0–60.8 % of the width and 35.9–95.1 % of the height. --backend cpu --vision-backend cpu runs it on the CPU, where the int8 file's coordinates move by a few thousandths from one process to the next: two runs boxed the truck as <58><359><610><952> and <60><359><612><951>. Its GPU and CPU runs wrote 5.11 GB of cache files next to the model, and the CPU run peaked at 7.6 GB of memory. With WeVisOne-VL-2B_f16.litertlm in place of the file name, the Mac GPU prints <ref>truck</ref><box><60><359><601><951></box>, <ref>crane</ref><box><939><152><1000><682></box>. Its two runs wrote 8.55 GB of cache files next to the model, 6.89 GB of it the CPU's float32 copy of the decoder weights, and with that cache its CPU run peaked at 19.3 GB of memory. --cache no writes no files but needs more memory: the float16 file's Mac CPU runs below, made that way, peaked at about 50 GB.

The source package (Tencent/WeVisOne-VL) asks each task with a fixed prompt, built by its build_prompt. Its templates, with {…} for your words, and an example of each; the fixed words are the package's, grammar included. Every picture question on this card used one of them, and free-form questions about a picture were not tested:
| Task | Template | Example |
|---|---|---|
| Detection | Locate all the instances that match the following description: {label}. {label}. (labels joined by ". ", a final ".") |
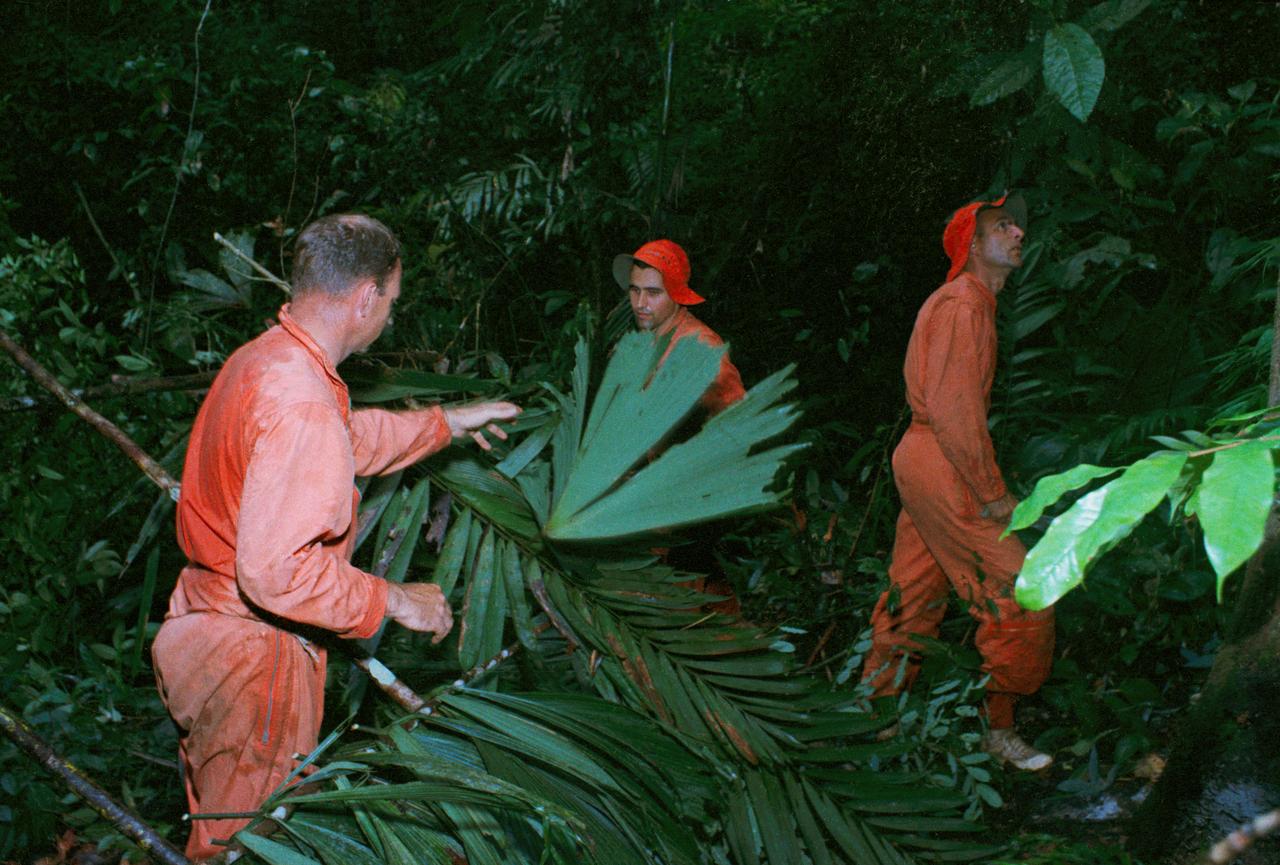
Locate all the instances that match the following description: person. hat. |
| Referring | Locate the instances that match the following description: {phrase}. (the package adds the final "." unless the phrase ends with ".", "?" or "!") |
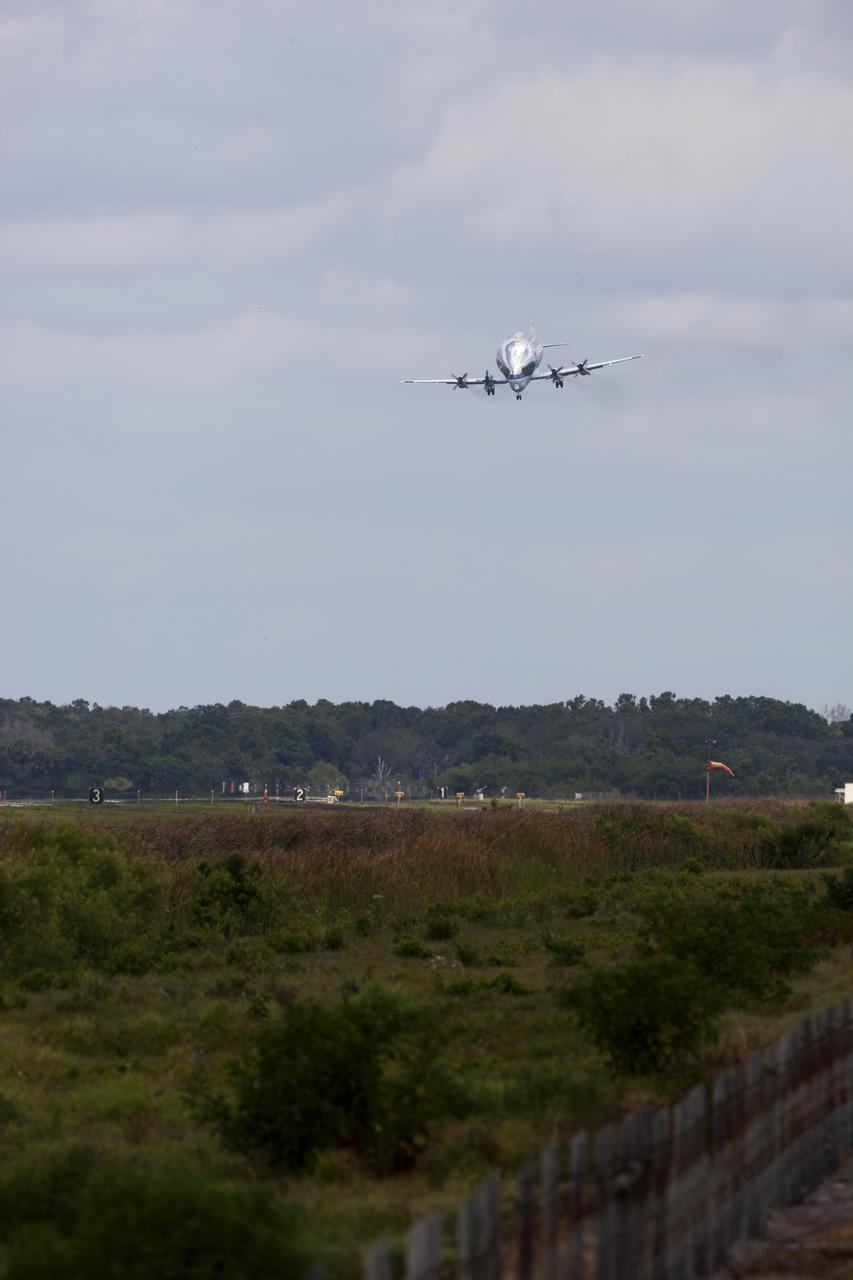
Locate the instances that match the following description: the airplane. |
| Pointing | point to: {label}. {label} (no final ".") |
point to: airplane. windsock |
| Counting with boxes | How many {objects} in the image? Please count them with boxes. |
How many airplanes in the image? Please count them with boxes. |
| Counting with points | How many {objects} in the image? |
How many people in the image? |
| OCR | detect all the word in the box format |
the same |
| Finding a text | Locate the following text in the image: {text} |
Locate the following text in the image: OVERSIZE LOAD |
Answers name each label in <ref>…</ref> and follow it with <box> or <point>: four tokens per box (left, top, right, bottom) and two per point (x, y), several boxes or points of one label separated by commas inside one tag, labels separated by ", ". The counting answers in the tests ended with Total number: N., also for "Counting with points", which answers with points. The source package's parsers read this format (parse_predictions in visualization.py, and parse_prediction in evaluation/utils/parser.py, through which every score on this card was computed). On the one test picture without the asked object (a radar image asked "How many airplanes in the image? Please count them with boxes."), the original at its own resolution and at 512 × 512, the float16 file on every backend, the int8 file on the Mac GPU and the int8 build marked * (Performance) on the Pixel 8a and Mac CPUs answered with one box over nearly the whole picture and Total number: 1.; the int8 file on the Galaxy S26 GPU answered <ref>airplanes</ref><box>none</box> and, on the next line, Total number: 1.
Three things to know when you call these files (only a second picture gives an error; a system message is ignored and a second question gets a changed answer, both without one):
- One picture per conversation, in the same first message as the question and before it (
--attachmentplaces it there). With a second picture LiteRT-LM 0.18.1 stops withINVALID_ARGUMENT: Provided more images than expected in the prompt. - The system turn is fixed to "You are a helpful assistant.", as in the source package; a system message you pass is not used.
- One question per conversation: start a new conversation, with the picture again, for the next question. From the second message on, LiteRT-LM 0.18.1 changes what the model sees (see Limits).
The files carry no sampler settings, so LiteRT-LM 0.18.1 decodes them greedily (top-k 1), and every answer on this card is greedy; sampled answers were not tested. With the float16 file, creating the engine takes longer than an answer (27.3 s on the Galaxy S26 GPU, against 4.2 s for the int8 file; see Performance), so keep the engine and open a new conversation per question: on the Mac GPU, five conversations in a row on one engine of the float16 file gave the same answers as one new process per question. Every other measurement here, and every phone run, started one process per question.
On Android the numbers below come from litert_lm_advanced_main, the command-line program built from the LiteRT-LM v0.18.1 tag: --backend=gpu --vision_backend=gpu on the Galaxy S26 and --backend=cpu --vision_backend=cpu --num_cpu_threads=4 on the Pixel 8a, with --max_num_tokens=2048 --input_prompt_file=<file>, the file holding [image:<path>] and then the question. An Android app integration was not tested, and the files' answers were checked on LiteRT-LM 0.18.1 only.
Performance
Picture columns: a synthetic 512 × 512 test picture (shapes and the text "EXIT 12", drawn by a script) and a detection question, 297 prompt tokens and 60 answer tokens. Text columns: the runtime's speed benchmark, 1,024 prompt tokens and 256 generated tokens in a 2,048-token context; it measures speed only (a text-only prompt that long gets wrong positions, see Limits).
| Device | File | Runtime, backend | Engine creation | Picture: first token | Picture: decode | Text: prefill | Text: decode | Text: first token | Peak memory |
|---|---|---|---|---|---|---|---|---|---|
| Galaxy S26 (SM-S942Q: Qualcomm SM8850, Adreno GPU; Android 16), 2026-10-31 | int8 | LiteRT-LM 0.18.1, GPU (OpenCL), vision on the GPU | 4.2 s | 1.26 s | 21.1 tok/s | 1,704.81 tok/s | 22.49 tok/s | 0.64–0.65 s | 2.70 GB (picture), 1.16–1.17 GB (text) |
| Galaxy S26, the same session | float16 | LiteRT-LM 0.18.1, GPU (OpenCL), vision on the GPU | 27.3 s | 1.54 s | 12.9 tok/s | 1,130.29 tok/s | 12.96 tok/s | 0.98 s | 6.86–6.90 GB (picture), 6.51–6.63 GB (text) |
| Pixel 8a (8 GB; Android 16), 2026-10-31 | int8 | LiteRT-LM 0.18.1, CPU (4 threads), vision on the CPU | 0.91 s | 13.58 s | 8.0 tok/s | 117.8 tok/s | 8.1 tok/s | 8.87 s | 4.43–4.57 GB (picture), 2.76–2.77 GB (text) |
| Mac M4 Max (macOS 27.0), 2026-10-24 | int8 | litert-lm 0.18.1, GPU (WebGPU on Metal) | 1.11 s | 0.29 s | 113.3 tok/s | 3,718 tok/s | 117.0 tok/s | 0.28 s | 3.85 GB (picture), 2.43 GB (text) |
| Mac M4 Max (macOS 27.0), 2026-10-24 | float16 | litert-lm 0.18.1, GPU (WebGPU on Metal) | 4.54 s | 0.30 s | 81.4 tok/s | 3,675 tok/s | 83.0 tok/s | 0.29 s | 8.0 GB (picture), 6.6 GB (text) |
| Mac M4 Max (macOS 27.0), 2026-10-24 | int8 * | litert-lm 0.18.1, CPU | 5.31 s | 4.64 s | 26.8 tok/s | 600 tok/s | 35.6 tok/s | 1.74 s | 15.6 GB (picture), 13.0 GB (text), both with --cache no |
| Mac M4 Max (macOS 27.0), 2026-10-24 | float16 | litert-lm 0.18.1, CPU | 5.70 s | 4.85 s | 12.6 tok/s | 506 tok/s | 14.9 tok/s | 2.09 s | 51.5 GB (picture), 49.7 GB (text), both with --cache no |
* Measured with an int8 build that differs from WeVisOne-VL-2B_int8.litertlm only in its file header: it declares float32 activations for the decoder (prefer_activation_type; the file's build id and date differ too), and every section of the two files is the same bytes. LiteRT-LM 0.18.1 uses that setting to choose the GPU's float16 or float32 precision (runtime/executor/llm_executor_settings_utils.cc); its CPU compile options do not read it, and on the Mac CPU the two float16 builds that differ in the same setting gave the same tokens on all 29 picture questions. On a CPU the two builds run the same computation, so the rows marked * stand for the published file; on a GPU they would not, so no GPU number of that build is given here.
- Galaxy S26: one session on 2026-10-31 that ran the two files in the order float16, int8, int8, float16, once for the picture question and once for the text benchmark; each value is the median of that file's two processes there. Before them, the first process of each file built its GPU caches (not counted: int8 1.13 s to the first token and 6.6 s of engine creation, float16 1.56 s and 33.3 s). Every counted process started with the phone at thermal status 1, the GPU at its top power level and no CPU clock cap. The picture's first token is the vision encoder's time (int8 0.85–0.88 s, float16 0.88–0.98 s) plus the runtime's time to first token (0.39 s and 0.61 s). After the engine, opening the picture conversation took another 5.4–5.5 s (int8) and 7.4–7.8 s (float16), the runtime's "Init Conversation" time. Peak memory is the process's peak resident memory (Linux's VmHWM counter, read from
/proc: int8 2,633,200–2,638,348 kB, text 1,137,380–1,141,584 kB; float16 6,696,088–6,737,728 kB, text 6,356,692–6,473,580 kB). The decoder and the vision encoder ran on the GPU in full with both files; the runtime runs the embedder and the adapter on the CPU. On 2026-10-25 the float16 file, one process per run as here, measured 1.53 s and 12.97 tokens per second on the picture question, 1,125.93 / 13.87 tokens per second of text prefill / decode, and 22.2 s of engine creation. - Pixel 8a: two processes per workload on 2026-10-31, median, after a first process that built the CPU caches (not counted). Each started at thermal status 1 without a CPU clock limit, and the phone lowered its CPU clock limit within every run (down to 60–78 % of the top frequency). VmHWM 4,325,164–4,462,788 kB (picture), 2,694,672–2,704,316 kB (text). All three of its picture runs gave the same answer as the build marked * gave in the Correctness test on this phone.
- Mac: text with
litert-lm benchmark -p 1024 -d 256 --max-num-tokens 2048 --cache no, pictures through the Python API without a cache; the picture's first token is the time to the first streamed text. Medians of 3 processes; engine creation is the picture processes' (Python API, no cache); peak memory is the process's maximum resident memory.
Correctness
Questions with a known answer
Eleven picture questions have an exact answer: 8 on two drawn test pictures (8 shapes to box, a referring phrase, the text "EXIT 12" to box and to read, a segmentation request's box, a count with boxes, a count with points and two points to place) and 3 on crops of the source package's example figures (a count of cups and a count of balls, from the figures' own numbers, and a referring question whose figure answer is "No target"). Ten text questions have an answer key (a sum, a product, an opposite, two capitals, a decimal comparison, "thank you" in French, a rhyme, the days of a week, and "What is my name?" after "My name is Ada."). On the same device a file may answer at most one box, count, point or no-target question fewer right than the float16 file, its OCR character error rate may be at most 0.02 higher, it must answer at least as many text questions right, and it must name Paris as the capital of France. We fixed this test on 2026-10-30, before scoring any file with it.
| Device, file | Boxes (of 11) | Counts (of 4) | Points (of 2) | No target (of 1) | OCR error | Text (of 10) |
|---|---|---|---|---|---|---|
| Galaxy S26 GPU, int8 | 11 | 3 | 2 | 0 | 0.000 | 9 |
| Galaxy S26 GPU, float16 | 11 | 2 | 2 | 0 | 0.000 | 8 |
| Pixel 8a CPU, int8 * | 11 | 2 | 2 | 0 | 0.000 | 9 |
| Mac GPU, int8 | 11 | 2 | 2 | 0 | 0.000 | 9 |
| Mac GPU, float16 | 11 | 2 | 2 | 0 | 0.000 | 8 |
| Mac CPU, int8 * | 11 | 3 | 2 | 0 | 0.000 | 9 |
| Mac CPU, float16 | 11 | 2 | 2 | 0 | 0.000 | 8 |
| The original in float32, 512 × 512 | 11 | 2 | 2 | 0 | 0.000 | 8 |
The Pixel 8a row is the build marked *; the published file's three picture runs on that phone gave the same answer as that build (Performance). Every int8 run passes (the Pixel 8a run against the Galaxy S26 float16 run, since the float16 file did not run on that phone). Each row is one process per question; on the Mac CPU an int8 answer's coordinates can move by a few thousandths between processes (Use it). The test is small: every run, the original included, finds all 11 boxes, places both points, reads "EXIT 12" and gets both counts on the drawn pictures; every run answers the no-target question with a box, and none counts the cups as the figure does. The files differ on the count of balls (the int8 file on the Galaxy S26 GPU and the build marked * on the Mac CPU answer the figure's 10; the float16 file answers 9, as does the original) and on one text question: after "My name is Ada.", the int8 file's second answer contains the name ("Ada! That's a lovely name. How can I assist you today?" on the Galaxy S26 GPU) and the float16 file's does not. LiteRT-LM 0.18.1 changes every second message of a conversation (Limits), and the float32 original itself answers that question without the name.
Agreement with the original model
These numbers say how far each file drifts from the original model's own answers, not whether an answer is right; use them when you need the same coordinates the PyTorch model gives. A closer look: how many of the float32 original's own boxes, counts and points a run reproduces, and the character error rate against the original's OCR text, on 29 questions over 17 pictures (2 synthetic test pictures, 4 NASA photos, 10 crops of the source package's example figures and its demo photo) across 9 tasks (the 7 above plus segmentation and matting, whose boxes are scored). The reference is the source package at 40f735b8 in float32 on the CPU, greedy, given the same 512 × 512 pictures. This counts every difference from the original, right or wrong; what the 512 × 512 input itself costs is under Limits. The first row is the original model itself run in bfloat16 and scored the same way.
| Run | Boxes (IoU ≥ 0.75) | Counts | Points (within 2 % of the side) | OCR character error rate |
|---|---|---|---|---|
| The original in bfloat16 | 55/55 | 5/6 | 38/44 | 0.000 |
| float16, Mac CPU | 55/55 | 6/6 | 42/44 | 0.000 |
| float16, Mac GPU | 55/55 | 6/6 | 39/44 | 0.000 |
| float16, Galaxy S26 GPU | 55/55 | 6/6 | 35/44 | 0.000 |
| int8, Mac GPU | 55/55 | 6/6 | 35/44 | 0.000 |
| int8 *, Mac CPU | 54/55 | 5/6 | 35/44 | 0.000 |
| int8 *, Pixel 8a CPU | 54/55 | 6/6 | 29/44 | 0.000 |
| int8, Galaxy S26 GPU | 49/55 | 4/6 | 28/44 | 0.226 |
Every point that differs in the float16 rows is on two questions whose float32 answers at 512 × 512 hold 9 and 23 points (crops of cups and of a pig; see Limits). The int8 file differs from the original more, and most on the Galaxy S26 GPU; its OCR error there comes from one picture (a crop of a sign from the source package's example figures), where it lists the words "World" and "Famous" in the other order, and in every OCR question it reads the same words as the original. Earlier versions of this card judged files by these numbers (boxes 90 %, counts 66.7 %, points 72.7 %, character error at most 0.05; the count and point thresholds are below 90 % because the original itself differs on 1 of 6 counts and 6 of 44 points in bfloat16, and they allow twice that). The int8 file misses them on the Galaxy S26 GPU, and the build marked * misses them on the Pixel 8a CPU; whether an answer is right is what the questions with a known answer above measure. A float32 build of the same graphs (not published) gives the original's tokens on all 29 picture questions on the Mac CPU and GPU, so the float16 file's differences there come from float16.
On-device answers (Galaxy S26 GPU)
| Picture (NASA, public domain) | Question | WeVisOne-VL-2B_int8.litertlm, verbatim |
WeVisOne-VL-2B_f16.litertlm, verbatim |
|---|---|---|---|
 |
detect all the word in the box format |
<ref>OVERSIZE LOAD</ref><box><114><786><352><860></box> |
<ref>OVERSIZE</ref><box><120><788><276><858></box>, <ref>LOAD</ref><box><274><792><351><858></box> |
 |
point to: airplane. windsock |
<ref>airplane</ref><point><607><282></point>, <ref>windsock</ref><point><848><601></point> |
<ref>airplane</ref><point><620><285></point>, <ref>windsock</ref><point><848><600></point> |
 |
Locate all the instances that match the following description: person. hat. |
<ref>person</ref><box><116><247><406><998>,<479><276><583><490>,<672><226><825><894></box>, <ref>hat</ref><box><479><276><551><357>,<736><226><795><323></box> |
<ref>person</ref><box><117><247><407><994>,<480><277><583><486>,<672><226><826><893></box>, <ref>hat</ref><box><480><277><551><356>,<736><226><796><323></box> |
The model got each original NASA file (KSC-08pd3809, KSC-20170424-PH_SWW01_0007, S67-34267) resized to 512 × 512; the pictures above are NASA's smaller copies for display. The answers are from 2026-10-25.
Masks: an Android app with the source model's pixel decoder
These files cannot cut things out: the source model's pixel decoder reads the language model's hidden state at the <OBJ> token, and a LiteRT-LM conversation returns the answer's text, not that hidden state. The cutout/ folder of this repository holds the model as separate LiteRT graphs for an app that runs them itself: the vision encoder and adapter (float16 weights), the 28-layer language model with int8 weights (1,785,462,176 bytes) or float16 weights, the pixel decoder (wevisone_mask_decoder_gs16.tflite, float16 weights), the token embeddings as a float16 table, and tokenizer.json. wevisone/ in LiteRT-Models is an Android app that runs them with LiteRT 2.3.0 CompiledModel on the GPU: pick a photo and type what to cut out, and it draws the box and shows the cut-out; Save PNG writes it as a transparent PNG. On a Galaxy S26 it took 4.7 s from a 640 × 480 test picture of coloured shapes and "the green circle" to the cut-out, and 5.8 s for a 3000 × 2029 photo (2026-10-25, the median of four runs after the first; the first run after install took 35.7 s, 30.5 s of it creating the three GPU graphs, which the later runs reuse). Against the source model in float32 at the same 512 × 512 input, its mattes on six test requests differ by at most 0.0032 in mean absolute alpha.
The app on a Galaxy S26 (2026-10-25): a photo of a kitten and a puppy (by blende12 on Pixabay, CC0, from Wikimedia Commons), the words "the kitten", the Run button, then a tap on the photo for the cut-out alone. The run in the clip took 4.9 s. It is not the app's first run after the install: that run builds the GPU graphs and took 35.6 s on the clip's install (the 35.7 s above is another install).
Limits
- Fixed 512 × 512 input. The source package chooses the resolution per picture. At 512 × 512 the float32 original reproduces its own native-resolution answers on 47 of their 56 boxes, all 6 counts and 12 of their 18 points, with OCR character error 0.105; the differences are in large photos and in small crops stretched up (on the crops of cups and of a pig it answers with 9 and 23 points, where it gives 5 and 1 at its own resolution).
- Text-only conversations past 270 tokens. In a conversation without a picture, every token after the 270th of the conversation, prompt and answer together (the system turn and the chat template count), gets a rotary position (the index the decoder's attention uses) 240 lower than the original gives it, because the decoder computes picture and text positions with one formula. A 353-token summary request broke down after 7 tokens. Conversations with a picture get the original's positions.
- The second message of a conversation. From the second message on, LiteRT-LM 0.18.1 passes the previous answer's stop token to the model with a zero embedding, so the second answer is not the model's own: after "My name is Ada.", the float16 file answers "What is my name?" with "You're asking about your name again? Hmm, maybe you want to know my name instead? I'm Qwen, …" where the original says "You're asking about your name, but you haven't provided it yet. …" (on the Mac CPU and the Galaxy S26 GPU; the Mac GPU's second answer differs in wording, not in kind), and the int8 file answers "Ada! That's a lovely name. How can I assist you today?" on the Galaxy S26 GPU. By the runtime's source it affects every LiteRT-LM 0.18.1 file with a separate embedder section (the graph that turns token ids into embeddings, which both files have) on the CPU and the GPU, not only these; a file of
litert-community/Qwen2.5-Coder-1.5B-Instructshowed it too. The cause in the runtime's source and a replay that reproduces it: the section "A runtime defect that every file with an embedder section meets" ofdocs/deepstack-wide-embedding.mdin hf-to-litertlm. Ask one question per conversation. - Memory. On the 12 GB Galaxy S26 the float16 file's GPU process peaks at about 6.9 GB, with the GPU at its default float16 activations, and the phone's free memory falls to about 1 GB during a picture question; the int8 file's process peaks at 2.7 GB. Our test harness stops a run when the phone's free memory falls below a set limit, so that the phone does not run out. On a Pixel 8a (8 GB) it stopped the GPU engine creation of the int8 build marked * at 592,360 kB (limit 600,000 kB); the int8 file on that GPU and the float16 file were not started there. On an iPhone 18 Pro, in our iOS test app with the LiteRT-LM v0.16.0 iOS framework (Metal), the float16 file never reached an answer: iOS ended the app at 6.45 GB in 3 of 3 launches, with the increased-memory-limit entitlement. The int8 file was not run on an iPhone, and LiteRT-LM 0.18.1 was not tried on one.
- Phone CPU (Galaxy S26). The CPU path expands the float16 weights to float32: on the Galaxy S26 CPU the float16 file decoded 0.14 tokens per second while the phone swapped. The int8 build marked * took 2.34 s to the first token of the picture question there and decoded 20.16 tokens per second (2026-10-24 to 25), slower than the int8 file on the Galaxy S26 GPU.
- NPU. This repository has no NPU build. On the Galaxy S26 the harness stopped the on-phone compile of the text decoder alone (int16 activations, int8 weights) 47 s in, with 889,412 kB of free memory left (its limit for that run was 1,000,000 kB) and the phone swapping; whether the compile would have finished was not tested. Neither file was compiled for the NPU.
- Repetition penalty. The source package generates with a repetition penalty of 1.05, which LiteRT-LM 0.18.1's sampler does not offer. The reference above is plain greedy; on the 29 questions, at the package's own resolution, the two differ on 1 of 18 points and on no box or count.
How it was converted
- DeepStack carried in full. Qwen3-VL adds three extra vision features (DeepStack) to the decoder after layers 0, 1 and 2, while LiteRT-LM's
fast_vlmtype gives the decoder one embedding per image token. Adding the three features into that one embedding changed the answers: boxes 41/55, counts 4/6, points 17/44 and OCR error 0.472 against the original. The files widen the embedding instead. Each image token carries 8,196 values: the main embedding, the three DeepStack features (3 × 2,048), an image flag and 3 zeros of padding. The decoder adds each DeepStack part after layers 0, 1 and 2, as the original does. LiteRT-LM copies image embeddings at the decoder's input width, so it passes the wide rows through. - Qwen3-VL's positions, computed in the graph. The runtime gives the decoder one position per token. The decoder computes Qwen3-VL's three-axis rotary positions from that position and the image flag; in conversations with a picture they equal the original's at every position checked (85,542 positions of 58 test prompts).
- The vision tower rewritten in plain PyTorch for a fixed 512 × 512 input, written without the gather op that mobile GPU runtimes do not accelerate, and converted to LiteRT graphs; on the Galaxy S26 the whole encoder runs on the GPU. The float16 encoder and adapter match the original's image features at a worst per-token cosine of 0.999995 (17 pictures).
- The int8 file is the same float32 export with int8 weights in the decoder and the token embedder (ai-edge-quantizer's
dynamic_wi8_afp32recipe: one scale per output channel; on the CPU the runtime also quantizes those layers' inputs to int8 as it runs), with the float16 vision encoder and adapter of the other file. - In both files the tokenizer section is the source repository's
tokenizer.json, byte for byte. - Other builds measured and not published. A float32 build (9.77 GB) is faster than the float16 file on the Mac CPU and reproduced all 44 points there (3.32 s to the first token of the picture question, 14.1 tokens per second; peak 50.9 GB without a cache); the conversion script builds it with
FP32=1. An int4 build (2.11 GB) reaches the first token of the picture question sooner on the Mac CPU (2.65 s) and decodes faster there (33.5 tokens per second) than the int8 build marked *, passes the known-answer test there with one count fewer than the float16 file, and reproduced only 20 and 25 of the original's 44 points on the Mac CPU and GPU; it was not run on a phone. The harness stopped a float16 build with float32 GPU activations on the Galaxy S26 at 479,412 kB of free memory (limit 700,000 kB), and a 768 × 768 build took 0.66 s to its first token on the Mac GPU against 0.30 s, while the original at 768 × 768 reproduces only 10 of the 18 points it gives at its own resolution.
Scripts and conversion notes: hf-to-litertlm, its REPRODUCE.md (the WeVisOne-VL-2B entry) and docs/deepstack-wide-embedding.md there.
License
Apache-2.0, as the source model tencent/WeVisOne-VL-2B. The source model card states its intended use: research in visual grounding, referring localization, pointing, counting, OCR localization, referring segmentation and image matting; it is "not intended to make autonomous high-impact decisions or to identify individuals".
- Downloads last month
- 87
Model tree for litert-community/WeVisOne-VL-2B
Base model
tencent/WeVisOne-VL-2B